 01
Supremacy Agentic Automation
Agents that finish the work, not just describe it
We build agentic systems that hold state, call your real tools, recover from failure, and stop at the boundaries you set — orchestration engineered for production, not a loop wrapped around a prompt.
Built for operations and engineering teams handing real work to agents
01Overview
OrchestrationAn agent that cannot be traced, replayed, or bounded is not a system — it is a liability with a chat interface. We build them as directed graphs with explicit state, so behaviour is inspectable and failure is recoverable.
01/ 02
Orchestration
Agents that behave like software
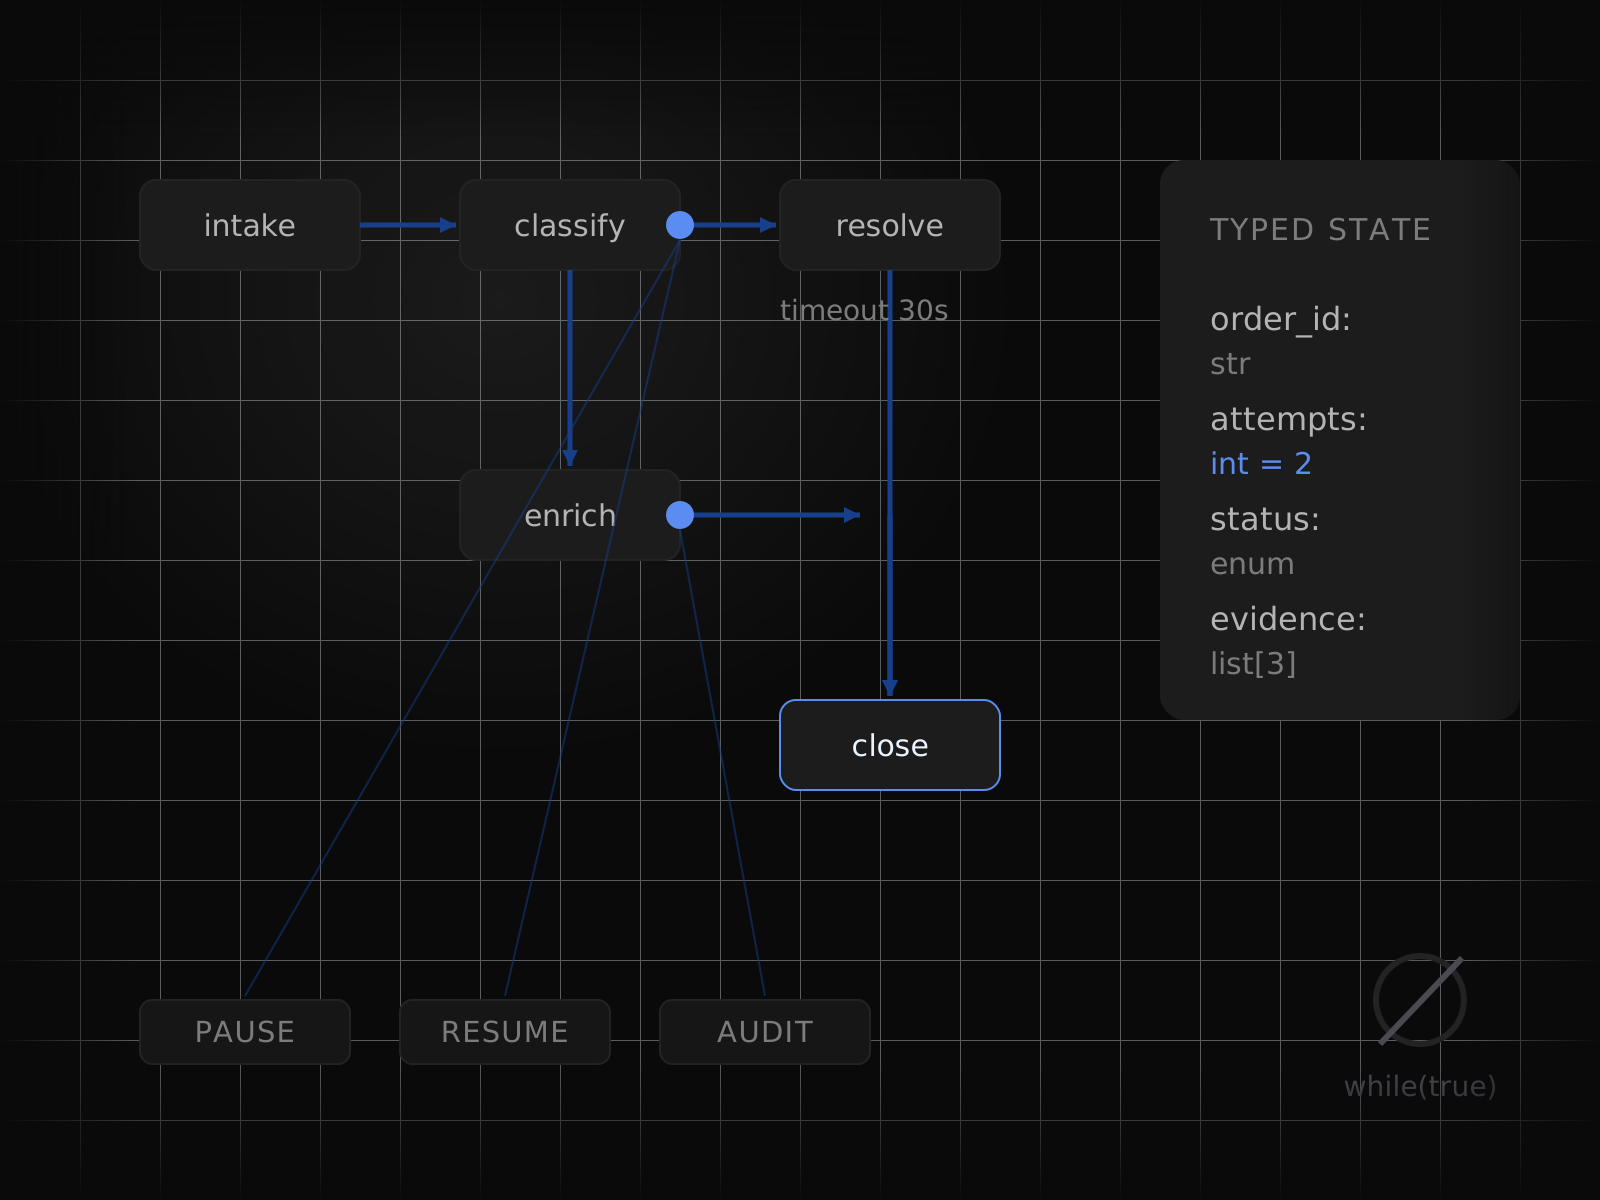
An agent that cannot be traced, replayed, or bounded is not a system — it is a liability with a chat interface. We build them as directed graphs with explicit state, so behaviour is inspectable and failure is recoverable.
- 01
Explicit state, not an open loop
Workflows are modelled as graphs with typed state, checkpoints, and per-node timeouts, so a long-running task can be paused, resumed, and audited step by step.
- 02
Tools behind a standard interface
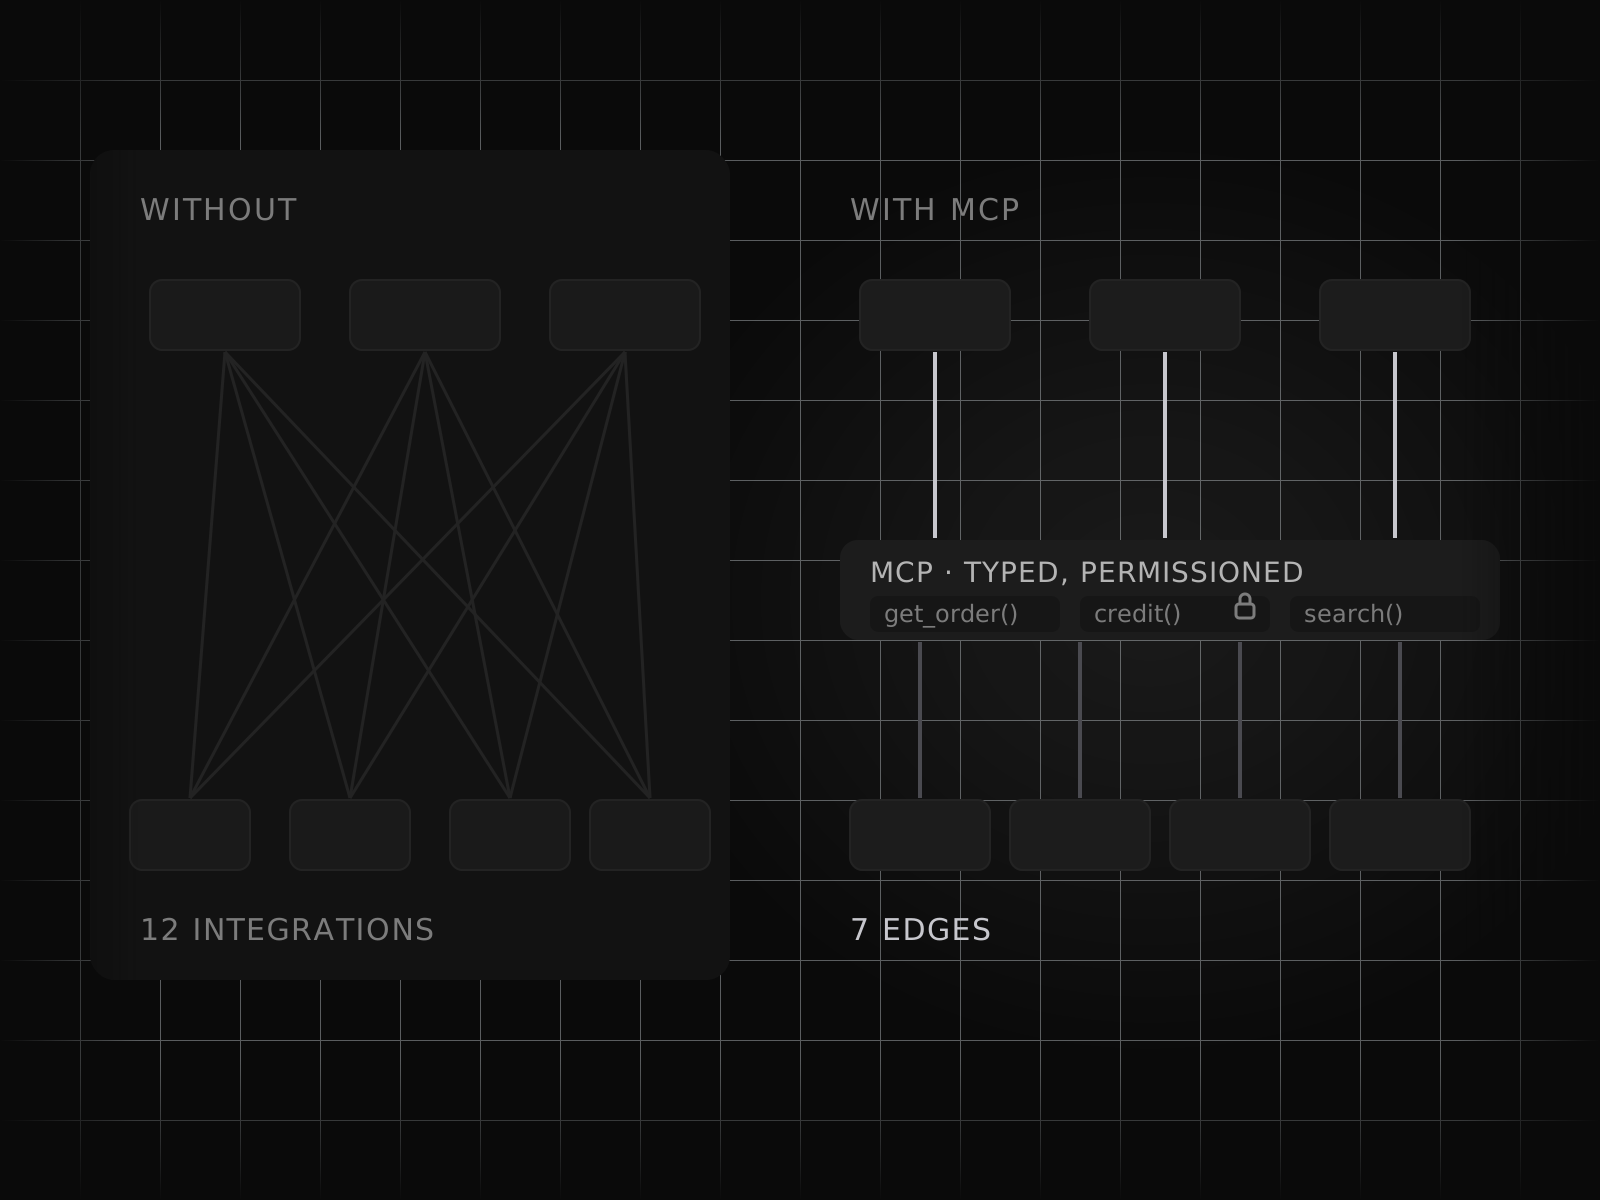
Model Context Protocol servers expose your systems as typed, permissioned tools, so one integration serves every agent instead of being rewritten for each framework.
- 03
Specialists over one giant prompt
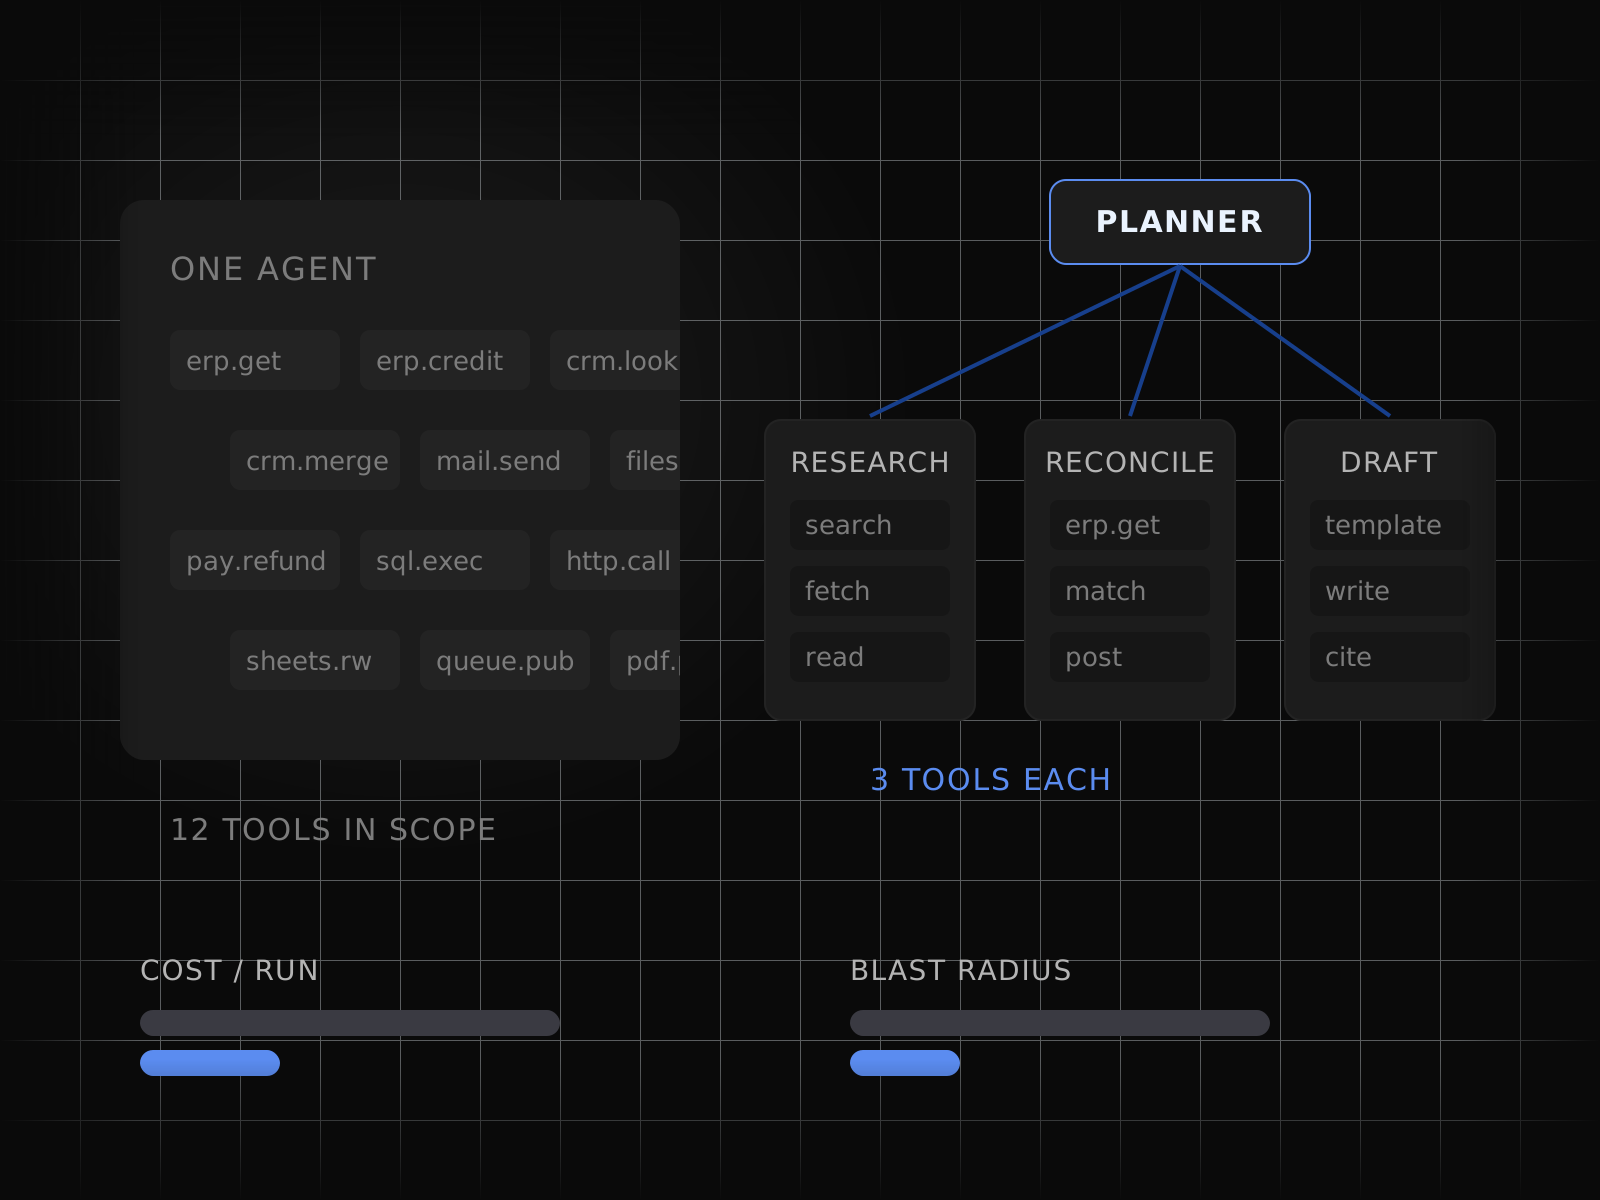
A planner delegates to focused sub-agents with narrow tool access, which is cheaper to run and far easier to debug than a single agent holding every capability at once.
- 04
Human in the loop where it counts
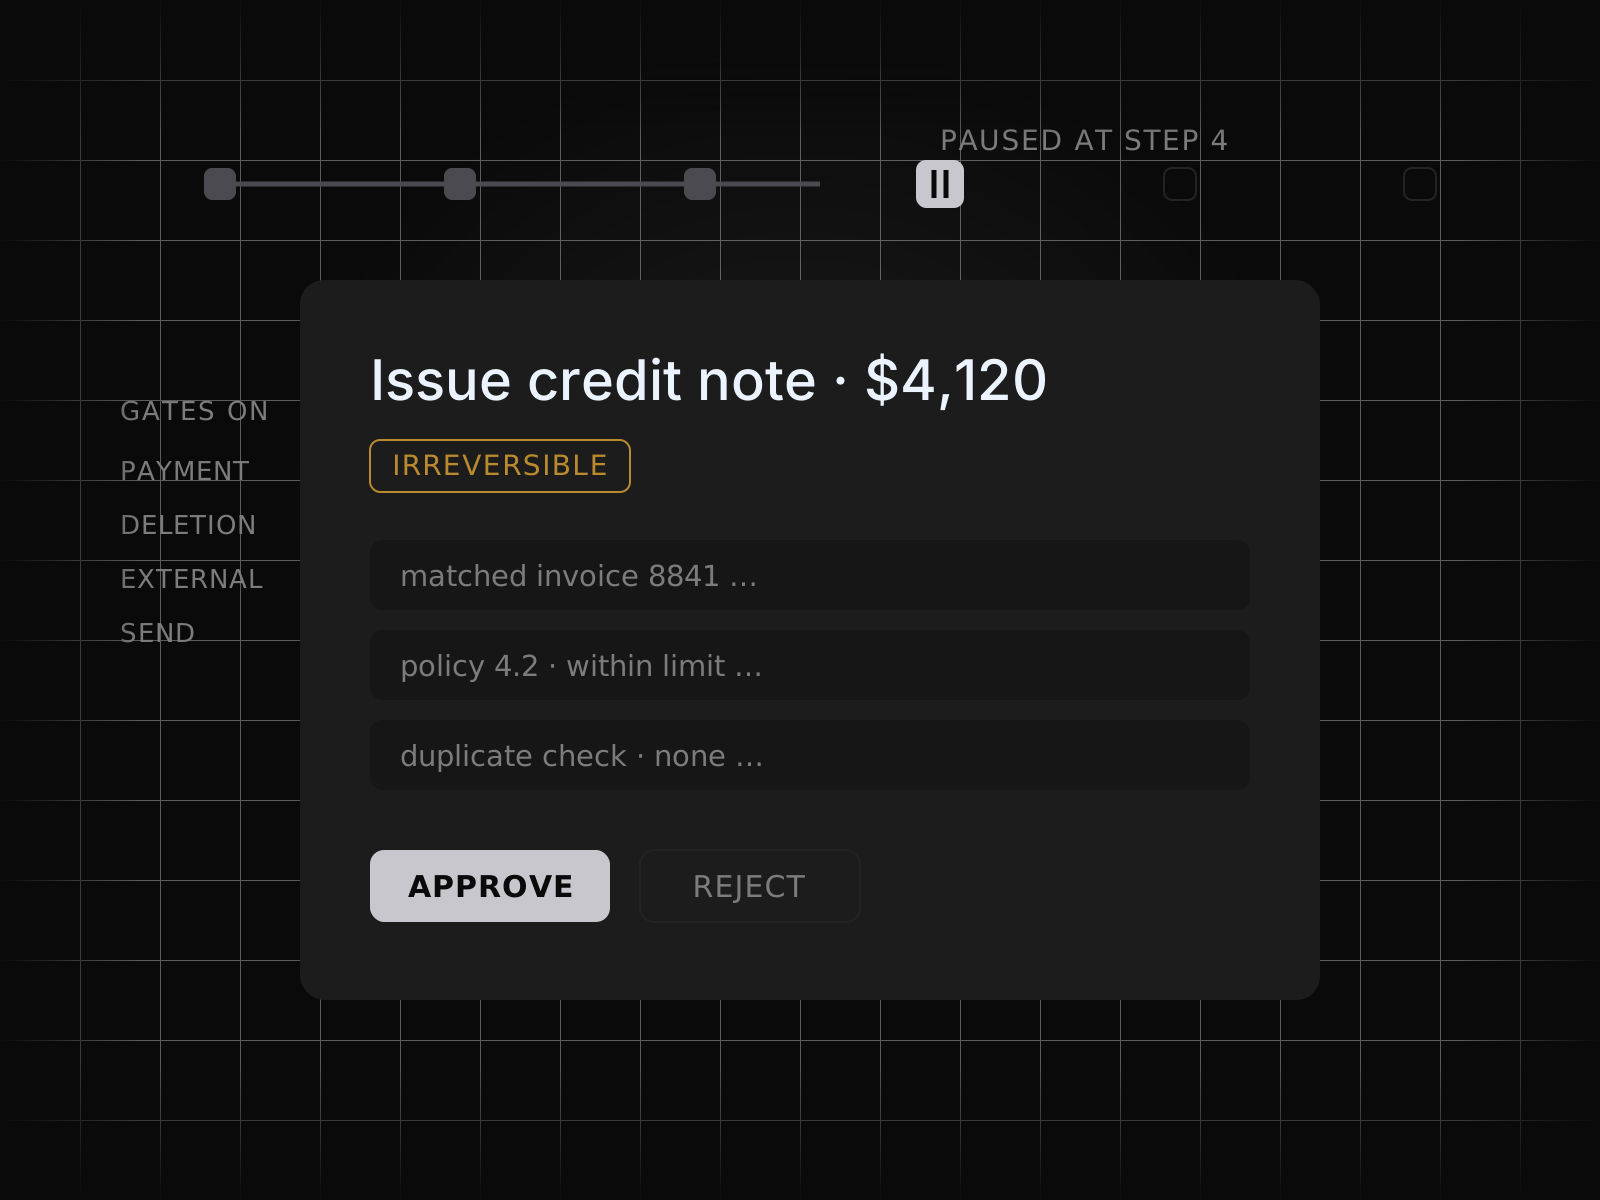
Irreversible actions — payments, deletions, anything leaving the building — pause for approval, with the full reasoning trace attached to the request.
02/ 02
Reliability
The difference between a demo and a deployment
Agents fail in ways ordinary services do not. They loop, they invent a tool argument, they take a plausible wrong path and commit to it. We instrument for exactly those, and cap what any single run can cost or touch.
- 05
Every run traced end to end
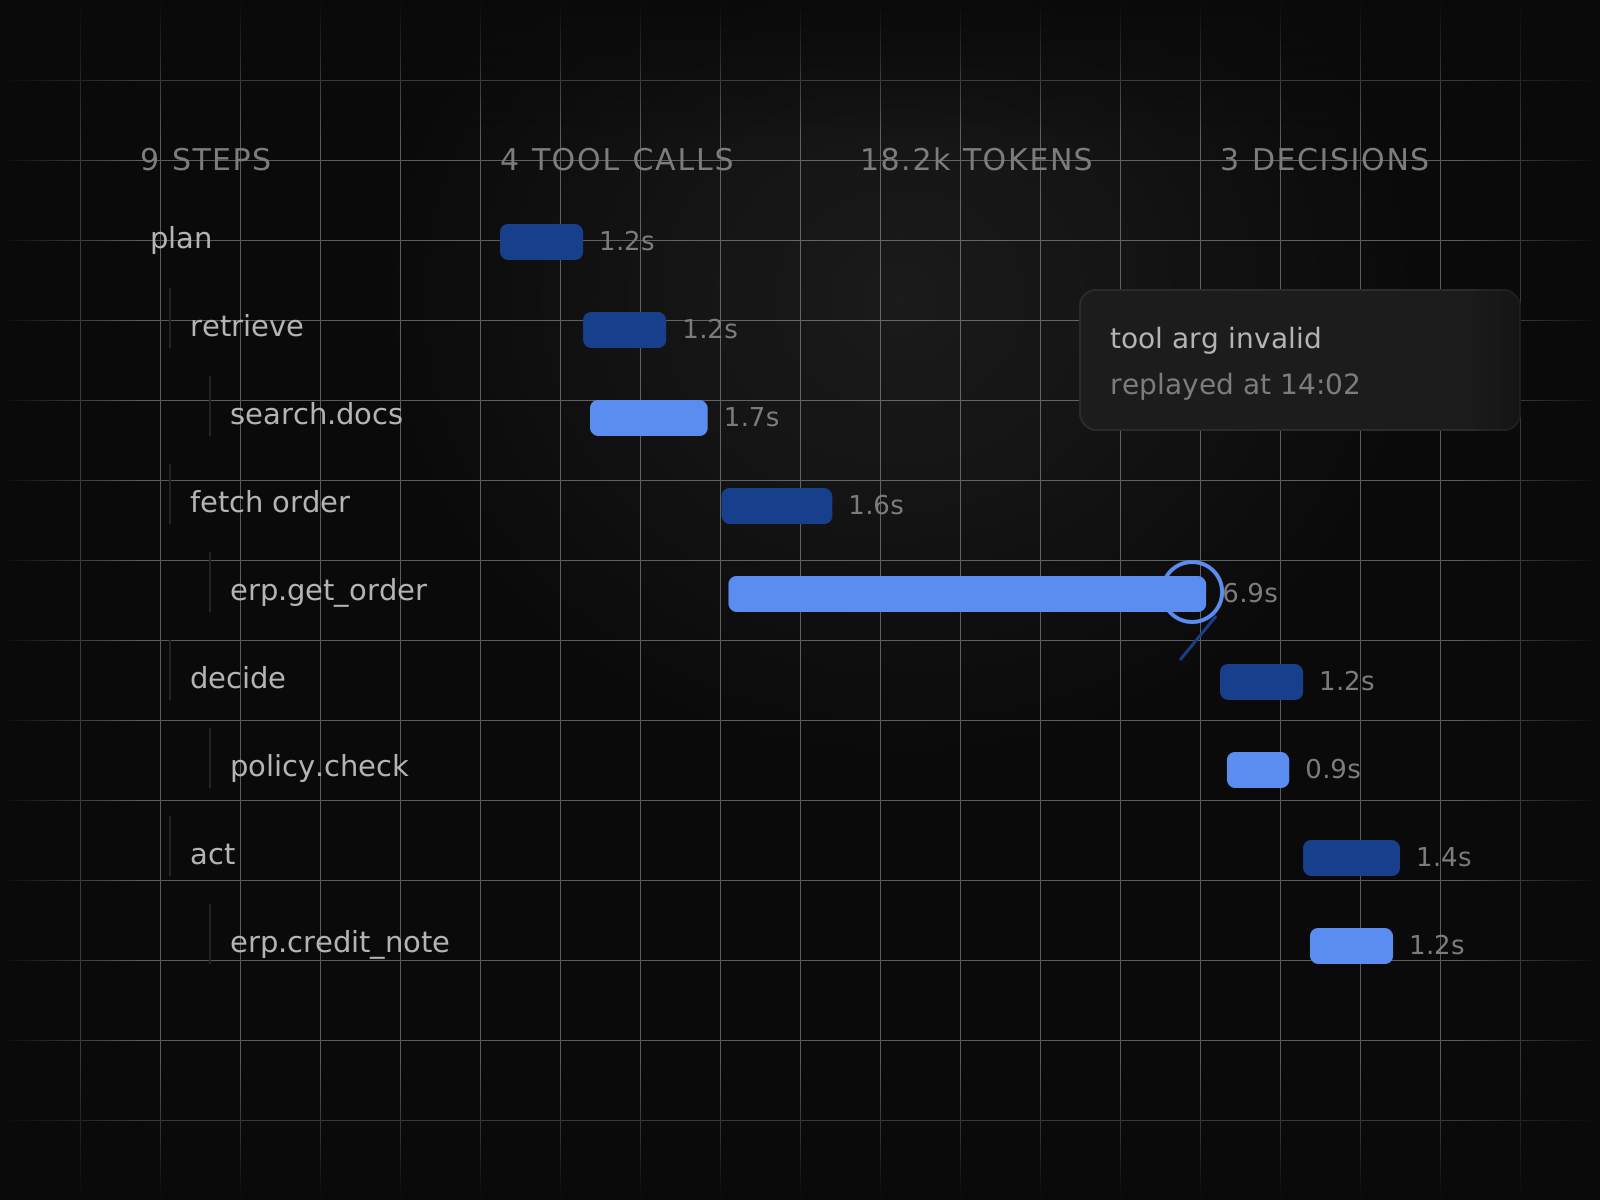
Each step, tool call, token, and decision is recorded, so a wrong answer gets replayed and diagnosed instead of guessed at in a retrospective.
- 06
Budgets that actually stop it
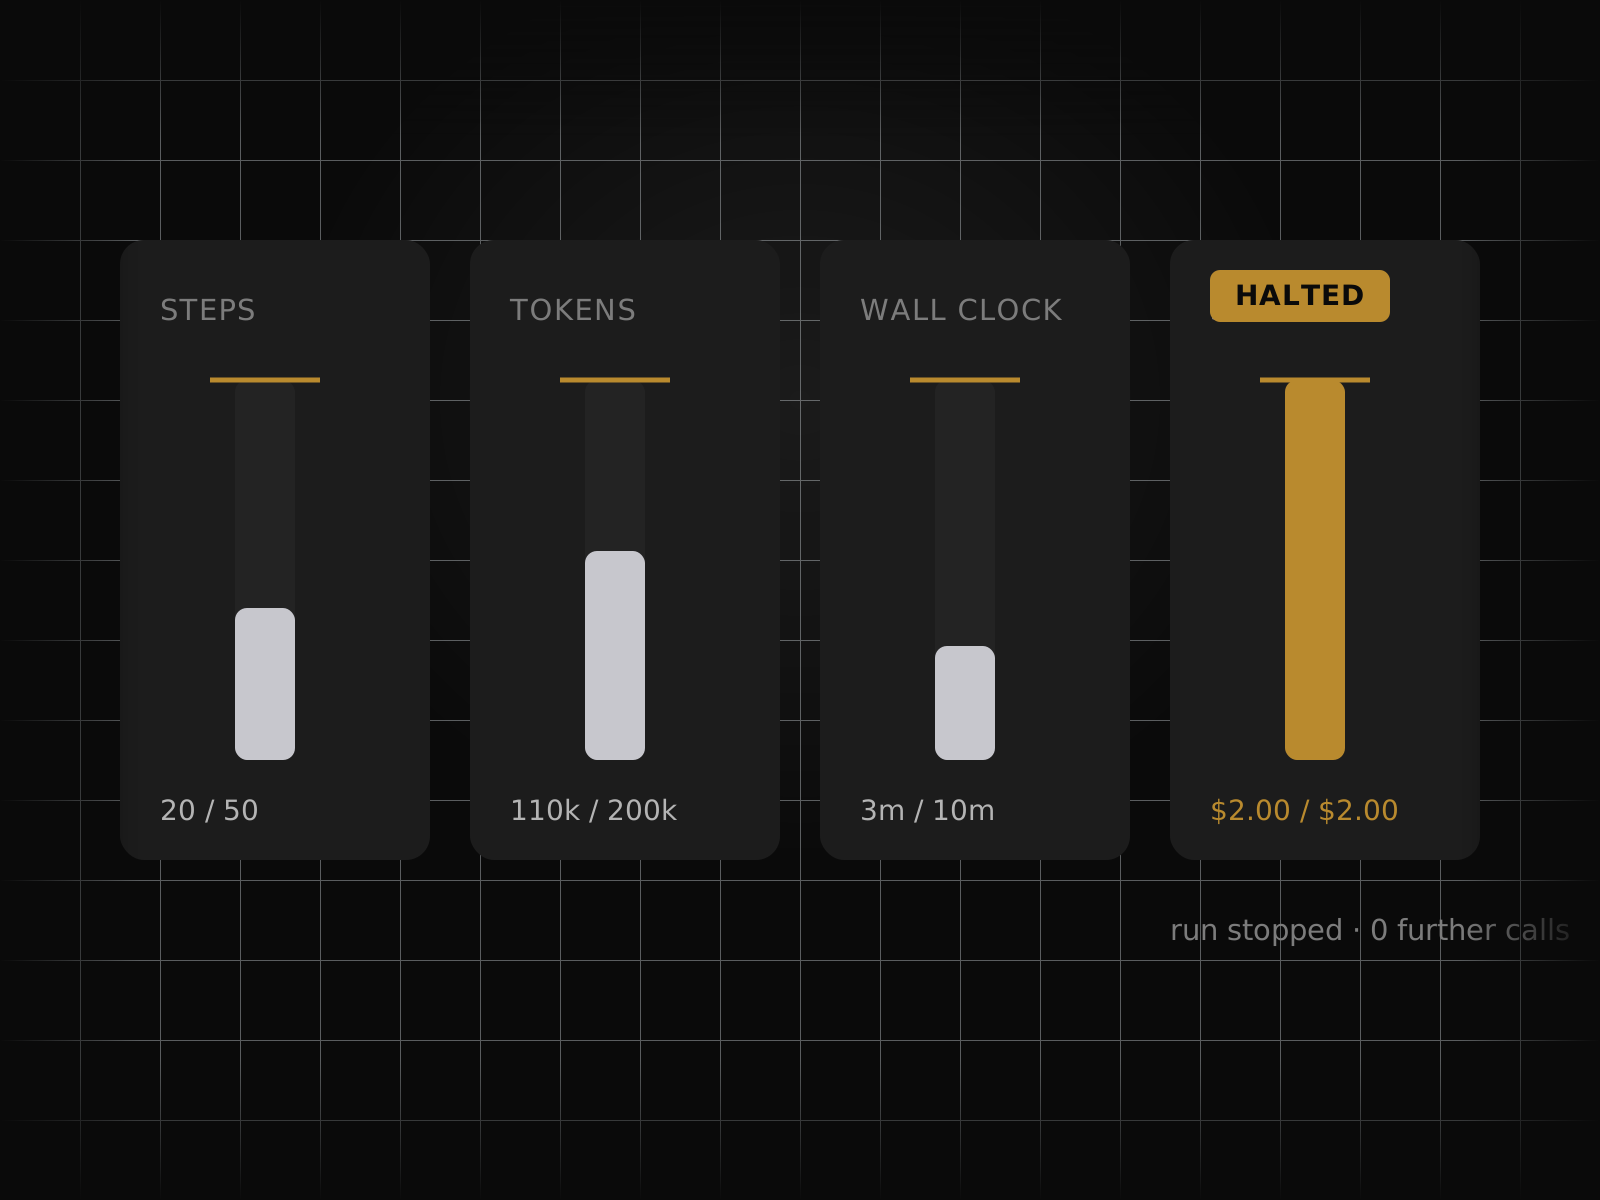
Per-run ceilings on steps, tokens, wall-clock, and spend mean a stuck agent costs a rounding error rather than a weekend of API charges nobody noticed.
- 07
Failure paths designed in
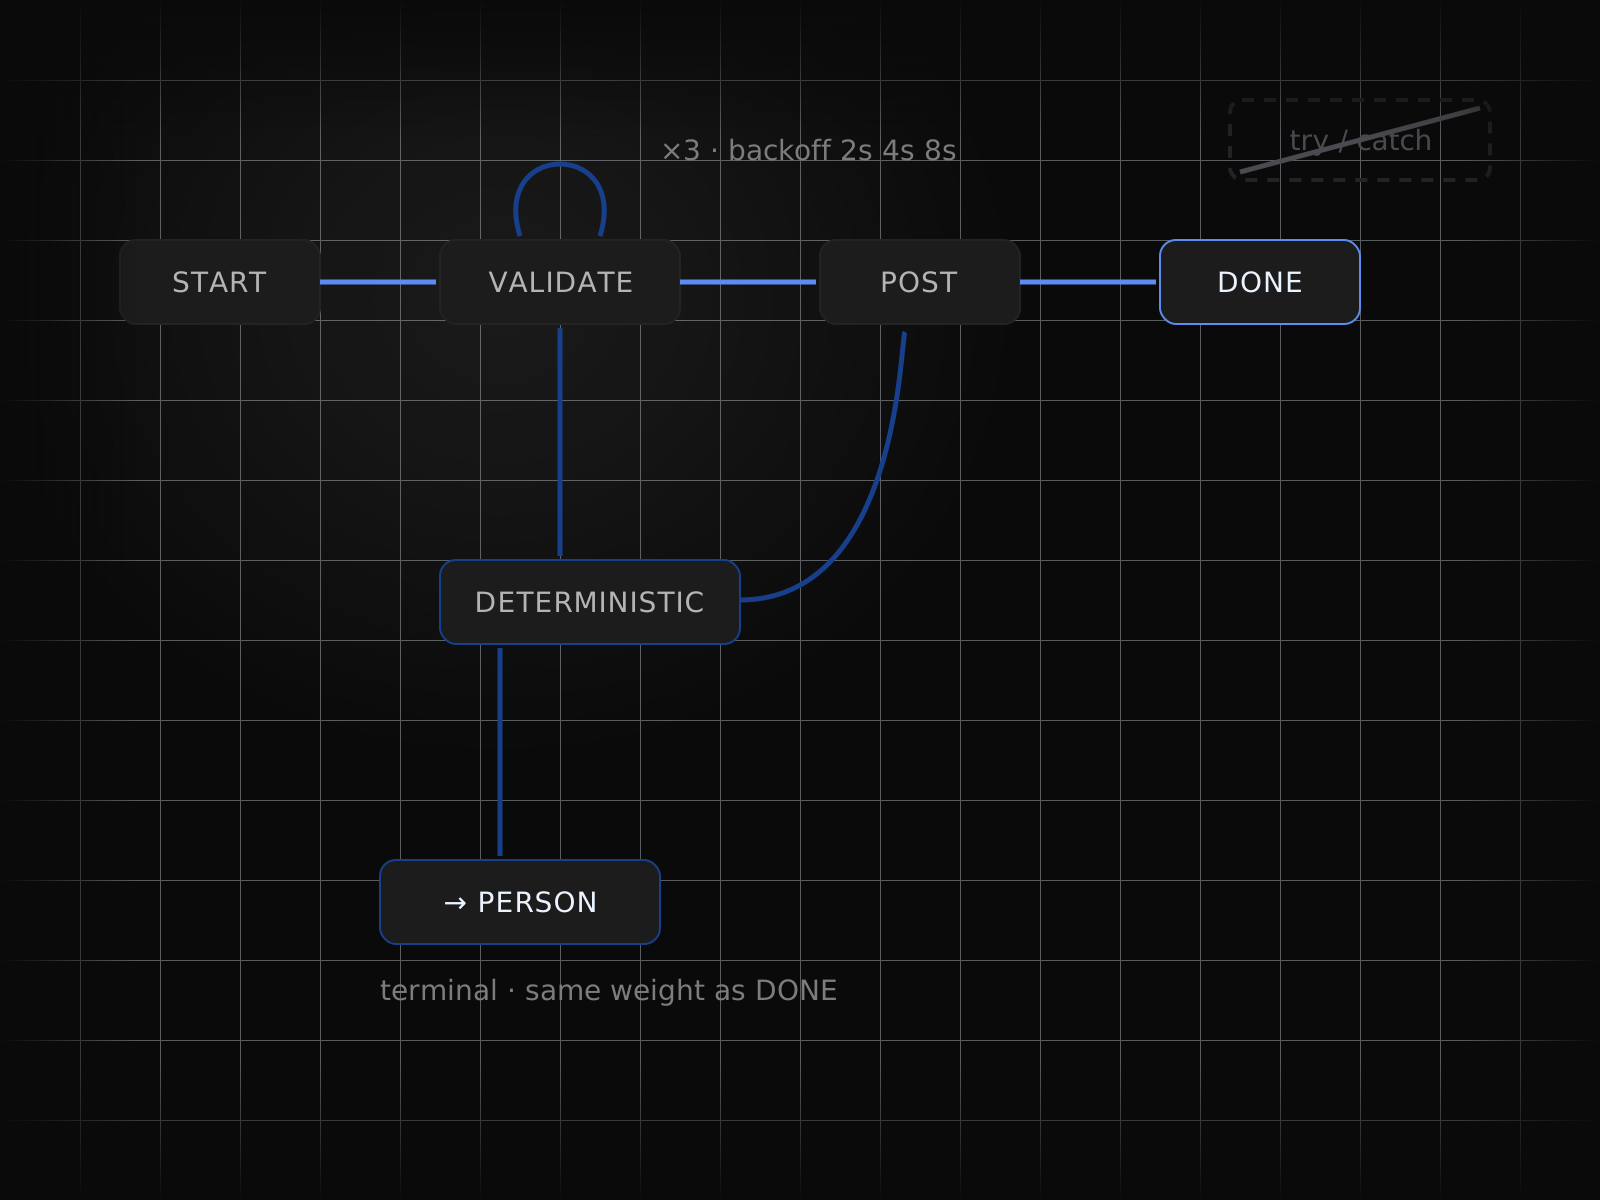
Retries with backoff, deterministic fallbacks, and escalation to a person are part of the graph, not an exception handler bolted on after the first incident.
- 08
Evaluation on whole trajectories
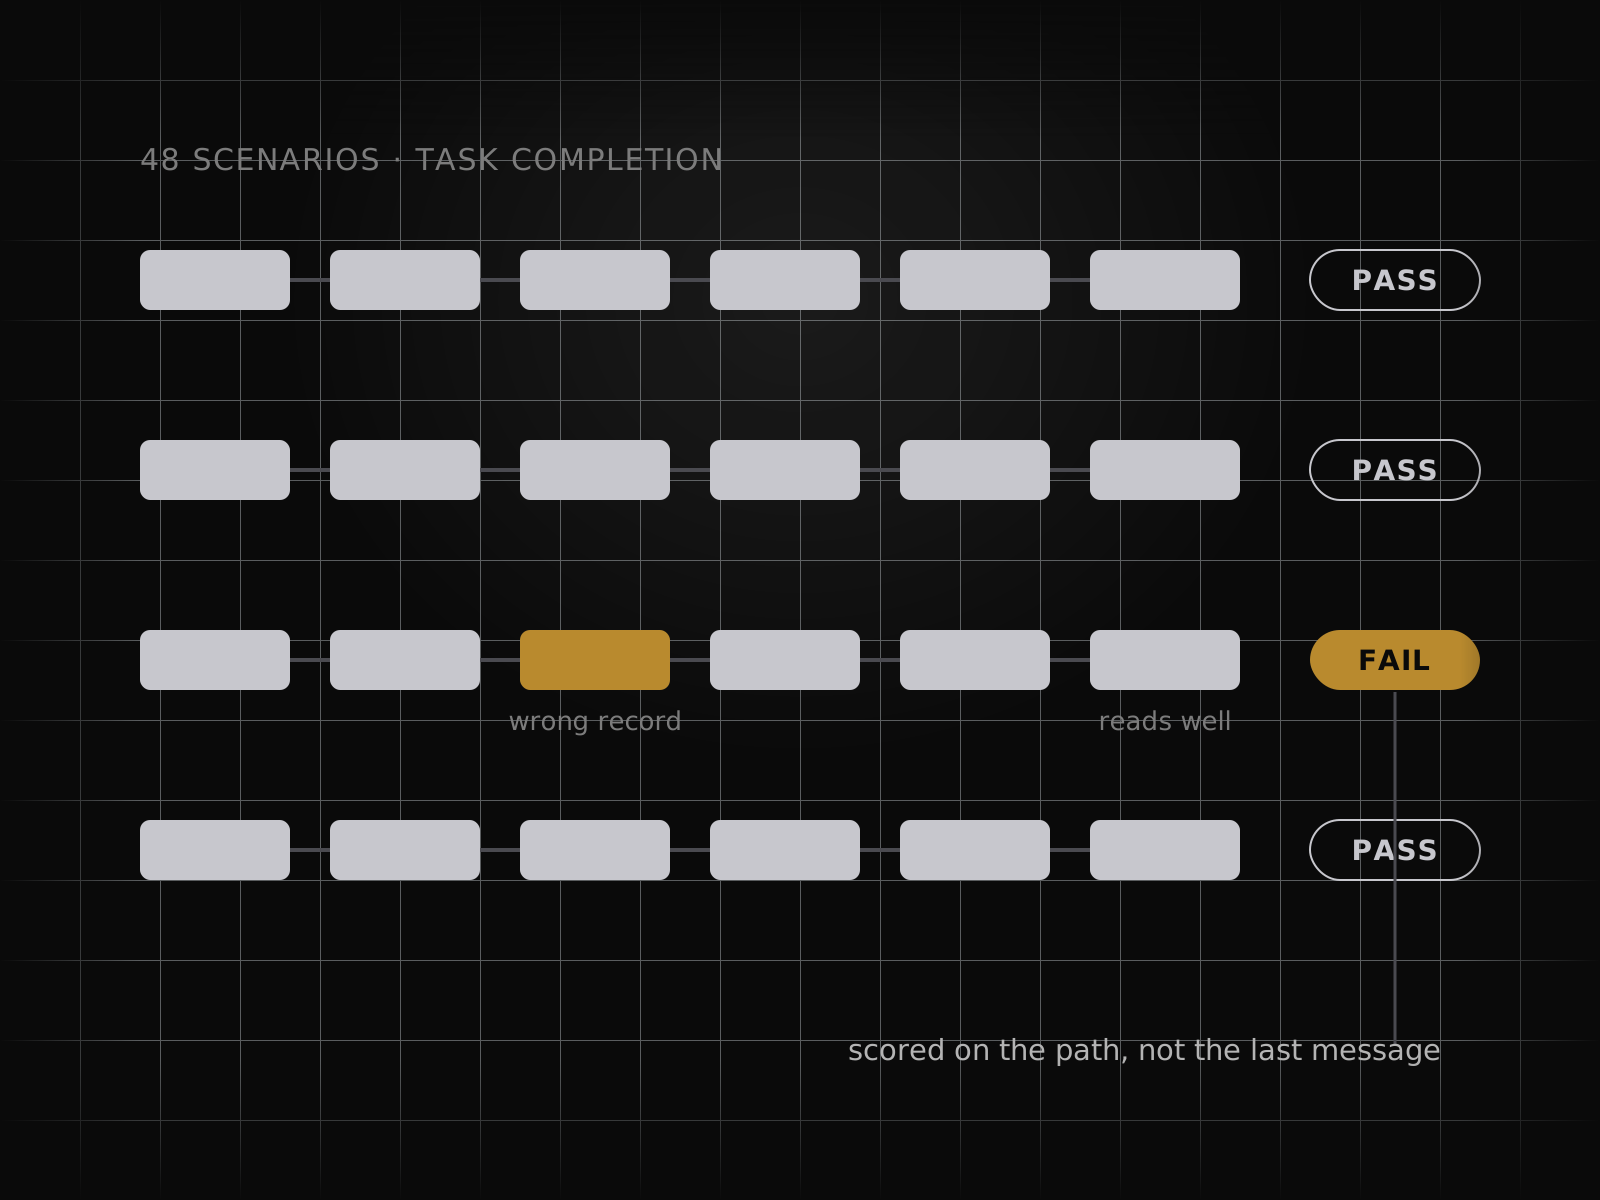
Agents are scored on whether the task completed correctly from end to end, not on whether the final message happened to read well.
At a glance
Every capability, at a glance
8 figures, one per capability. Open any to read it in full.
How it runs
From first call to running unattended
Every engagement runs the same five steps, whatever the service.
- 01
Map the process
We sit with the people who do the work today and write down every step, exception and hand-off before anything is built.
- 02
Build against a golden set
A held-out set of real cases, agreed with you, is the bar each build has to clear before it goes anywhere near production.
- 03
Run beside the team
The system runs in parallel with the team for as long as it takes, and every disagreement between them is reviewed together.
- 04
Hand over the keys
The code, the prompts, the evaluation set and the runbooks are handed over in your accounts, under your keys.
- 05
Keep it running
We watch the runs, retrain and repair as the inputs drift, or train your own team to do the same.
Outcomes
What this looks like when it lands.
01 An agent that clears the exception queue overnight
Orders that fell out of the automated flow are now investigated, enriched from three systems, and either resolved or escalated with a written rationale, so the morning queue starts near empty.
02 Procurement research that used to take an analyst a day
A planner agent gathers supplier data, checks it against internal policy, and produces a sourced comparison for review — with the human approval step kept exactly where the spend decision sits.
03 One tool layer, four agents, no rewrites
Exposing internal systems as Model Context Protocol servers meant each new agent inherited the same permissioned tools, taking integration work off the critical path for every subsequent build.
Details
On the spec sheet.
- Service
- AI Agents & Agentic Automation
- Group
- Agents & automation
- Capabilities
- 8
- Engagement
- Map, build, run beside the team, hand over, keep running
- Ownership
- Your accounts, your keys, your region
FAQs
Asked before signing.
What is agentic work actually good at today?
Multi-step tasks with unstructured input and a checkable result: triaging exceptions, researching and summarising against internal policy, reconciling records across systems, drafting work that a person approves. Where the path is fixed and the input is clean, deterministic automation is still the better answer.
Which frameworks do you build on?
LangGraph for core orchestration where state and durability matter, with Model Context Protocol as the tool interface so integrations outlive any one framework. We pick per workload and document why, rather than committing you to a single vendor’s runtime.
How do you stop an agent doing something expensive or irreversible?
Three ways at once: scoped tool permissions so it can only reach what it needs, hard per-run budgets on steps and spend, and a human approval gate on any action that cannot be undone. The limits are enforced by the orchestration layer, not by asking the model nicely.
How is this different from RPA?
RPA follows a fixed path through a known interface and is very hard to beat when the process is stable. Agents cover the cases where the path varies — unstructured input, judgement calls, exceptions. Most of our deployments run both, with the agent picking up whatever falls out of the deterministic flow.
How do you measure whether it is working?
Task completion rate on a fixed set of scenarios, plus cost and latency per run and the share of runs needing human intervention. Those numbers are tracked per release, so a change that makes the agent chattier but less effective is visible immediately.